How Much VRAM Do You Need for AI Image Generation in 2026?
Introduction
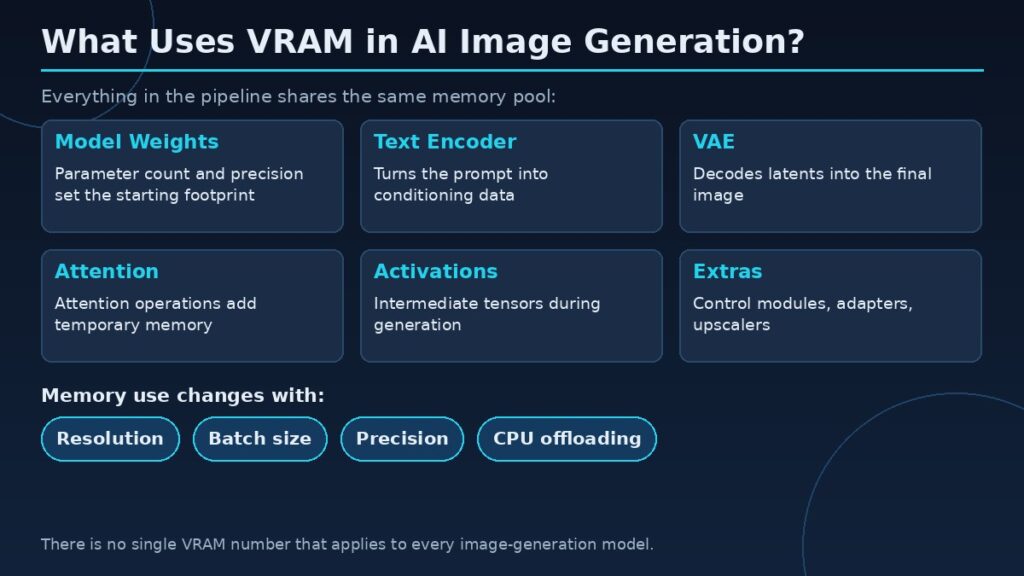
AI image generation can run on a wide range of hardware, but the experience changes considerably with model architecture, image dimensions, precision, batch size, and software implementation. A GPU with limited VRAM may still run some workflows through memory-efficient settings or CPU offloading, while a larger model or high-resolution generation process may need substantially more capacity. There is no single VRAM number that applies to every image-generation model.
This guide is designed to answer the practical question behind the headline, explain the technical principles involved, and give readers a repeatable way to evaluate their own hardware. Graphics memory is often discussed as if it were a single performance number, but real workloads are more complicated. The amount of memory installed, the amount currently allocated, the amount actively needed, the speed of the memory subsystem, and the work performed by the GPU core are related but distinct factors.
A useful analysis starts by identifying the workload. A game, an AI model, a 3D scene, and a video-editing timeline can use the same graphics card in very different ways. Each application creates its own resource footprint and responds differently when memory becomes constrained. The same capacity can be comfortable in one task and limiting in another. For that reason, this article avoids universal claims and explains which variables should be checked before making a decision.
| Factor | Effect on VRAM use |
|---|---|
| Model weights | Parameter count and precision give a rough estimate of weight storage |
| Image resolution | Higher output resolution increases intermediate feature maps and attention requirements |
| Batch size | More images together increases memory demand |
| Precision and attention optimizations | Reduced precision or optimized attention can lower memory use |
| Offloading and tiling | Moves components to CPU or splits work into sections; slower |
Quick answer
Select a GPU based on the exact image-generation pipeline, not a generic VRAM chart. Test the intended model, resolution, batch size, and extensions before buying.
The central rule is to measure the workload you actually run, not to assume that a specification or monitoring number tells the whole story. Where possible, compare equivalent settings, record repeatable measurements, and separate capacity limits from compute, bandwidth, CPU, storage, and software limitations.
Why image-generation memory use varies
A generation pipeline may load model weights, text encoders, a variational autoencoder, attention components, temporary activations, and intermediate tensors. Some pipelines also use control modules, adapters, upscalers, or multiple conditioning networks. The memory footprint therefore depends on the complete pipeline rather than the headline model name alone. Software versions and memory optimizations can materially change the result.
Model weights are only the starting point
A model’s parameter count and numerical precision provide a rough way to estimate weight storage. Lower-precision formats generally require less memory than higher-precision formats, but actual runtime use includes more than weights. Activations, temporary buffers, attention operations, and workspace allocations add overhead. A model that appears to fit on paper may still fail when the full pipeline starts.
Resolution and batch size
Higher output resolution can increase the size of intermediate feature maps and attention-related computations. Batch size controls how many images or samples are processed together and can increase memory demand. Generating one image at a moderate resolution is a different workload from generating several high-resolution images in one batch. If an out-of-memory error occurs, test a smaller batch and resolution before changing multiple other variables.
Precision and memory-efficient attention
Some frameworks support reduced precision or optimized attention implementations that can lower memory consumption or improve throughput. Availability depends on GPU architecture, drivers, framework versions, and model support. Reduced precision can have quality or compatibility implications, so use documented settings and compare output quality. Do not assume every optimization works with every checkpoint.
Offloading and tiled workflows
CPU offloading can move some model components or intermediate data out of GPU memory. This may allow a workflow to run on a smaller card, but transfers can reduce speed and increase system RAM requirements. Tiled decoding or tiled upscaling can split a large task into smaller pieces, though seams or output differences may need attention. These techniques are workarounds, not equivalent to having a larger local memory pool.
How to choose a GPU
Consider VRAM capacity, compute performance, memory bandwidth, supported precision formats, software compatibility, power consumption, and price. If you intend to use multiple models, large batches, high-resolution output, or complex conditioning pipelines, extra capacity can reduce compromises. If your use is occasional and lightweight, a more affordable GPU may be adequate. Check the requirements and community-tested configurations for the exact software you plan to use.
A reproducible test checklist
Record the model checkpoint, software release, GPU, driver, precision, attention backend, image dimensions, batch size, enabled extensions, and offloading settings. Note peak VRAM use and whether the run completed successfully. If comparing GPUs, use identical settings and distinguish generation time from setup and model-loading time. Save a sample output so that speed comparisons do not ignore quality differences.
A practical evaluation workflow
Start by documenting the exact hardware and software configuration. Record the GPU model, installed memory capacity, driver version, operating system, application version, CPU, system memory, and storage device. In a laptop or compact system, also note power mode and thermal conditions because those can change sustained performance. For a game, write down resolution, texture quality, ray tracing, upscaling, frame generation, and the exact scene or benchmark route. For an AI workflow, record model name, quantization, context length, batch size, framework, and whether layers are offloaded to CPU.
Next, establish a baseline. Close unnecessary applications, allow the workload to reach a steady state, and repeat the same task several times. Record average performance as well as low-percentile behavior or completion time. Capture memory allocation and system RAM use, but do not interpret either number alone. If the application exposes logs, save them. A screenshot is useful for documenting settings, while a CSV or frame-time trace is better for later comparison.
Change one variable at a time. If you change resolution, texture quality, batch size, model quantization, and driver version together, it becomes impossible to know which change produced the result. A controlled test can reveal whether a setting affects memory capacity, compute load, bandwidth, or simply image quality. Repeat the test after each change and note any visual or functional differences.
Finally, report the limitations. State whether the result came from a built-in benchmark, a repeatable manual route, a synthetic test, or a single real project. Explain whether the test was repeated and whether the measurement tool reports allocated, reserved, or actively used memory. Honest methodology makes an article more useful than a confident headline supported by an unexplained number.
Common mistakes and misleading conclusions
One common mistake is treating memory allocation as proof of memory exhaustion. Applications may reserve unused capacity for caching, and monitoring utilities do not all report the same metric. Another mistake is assuming that more capacity automatically increases performance. Extra memory helps when the workload needs it; it does not make shader cores faster or increase the speed of a narrow memory bus.
A third mistake is comparing different graphics cards as though memory capacity were the only difference. GPU architecture, core count, memory bandwidth, power limits, cooling, and driver maturity can all affect results. If two products differ in several ways, describe the comparison as a product-level test rather than a controlled memory-capacity experiment.
It is also easy to overlook software versions. Game patches can change asset streaming, shader compilation, and graphics settings. AI frameworks can change memory allocation strategies between releases. A result should therefore include a date and version information, and older findings should be retested before being presented as current advice.
Frequently asked questions
Can AI image generation run on 8GB VRAM?
Some models and workflows can run with careful settings, reduced batch size, memory-efficient attention, or offloading. Larger models and complex pipelines may need more.
Does higher image resolution use more VRAM?
It often increases intermediate tensor and buffer requirements, though the exact scaling depends on the model and implementation.
Does batch size affect VRAM?
Yes. Processing more samples together commonly increases memory demand.
Is CPU offloading a replacement for more VRAM?
It can make some workflows possible, but it may be slower and requires sufficient system RAM.
Is more VRAM always faster for image generation?
No. Compute capability, software support, memory bandwidth, and model optimization also affect generation speed.
Conclusion
Select a GPU based on the exact image-generation pipeline, not a generic VRAM chart. Test the intended model, resolution, batch size, and extensions before buying.
The most reliable decision comes from matching the hardware to a clearly defined workload and validating it with repeatable evidence. Use specifications to narrow the options, use measurements to understand actual behavior, and explain the limits of every comparison. That approach helps readers make a better decision without confusing a single memory figure with total graphics performance.









