What Is KV Cache in LLMs and How Much VRAM Does It Consume?
Introduction
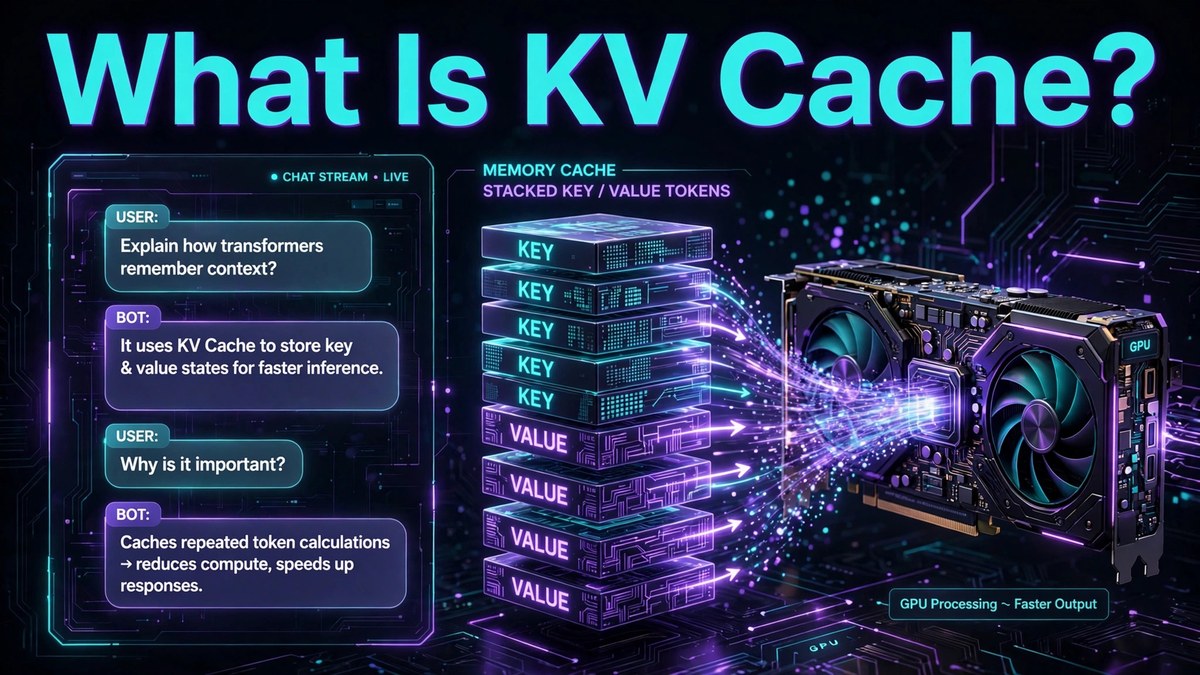
The key-value cache, commonly called the KV cache, is one of the reasons a language model’s runtime memory use can grow as a conversation or prompt becomes longer. During autoregressive generation, a model processes tokens and uses attention to relate current tokens to earlier ones. Rather than recomputing every earlier key and value representation from scratch for each new token, many inference systems retain them in a cache. This improves efficiency, but the stored information consumes memory.
Graphics memory is a finite working space, but the way an application uses it is shaped by its engine, data structures, runtime settings, and hardware. A useful guide must therefore explain both the general principle and the conditions that can change the outcome. The same GPU can behave differently after a software update, with a different model or game scene, or when another application is using the graphics processor.
This article focuses on practical understanding rather than a universal rule. It explains the terminology, identifies the variables worth checking, and provides a repeatable approach for evaluating a real system. Where a result depends on a specific application, that dependency should be made explicit instead of turning one observation into a claim about every workload.
| Factor | Effect on KV cache size |
|---|---|
| Longer context | Cache generally grows with sequence length |
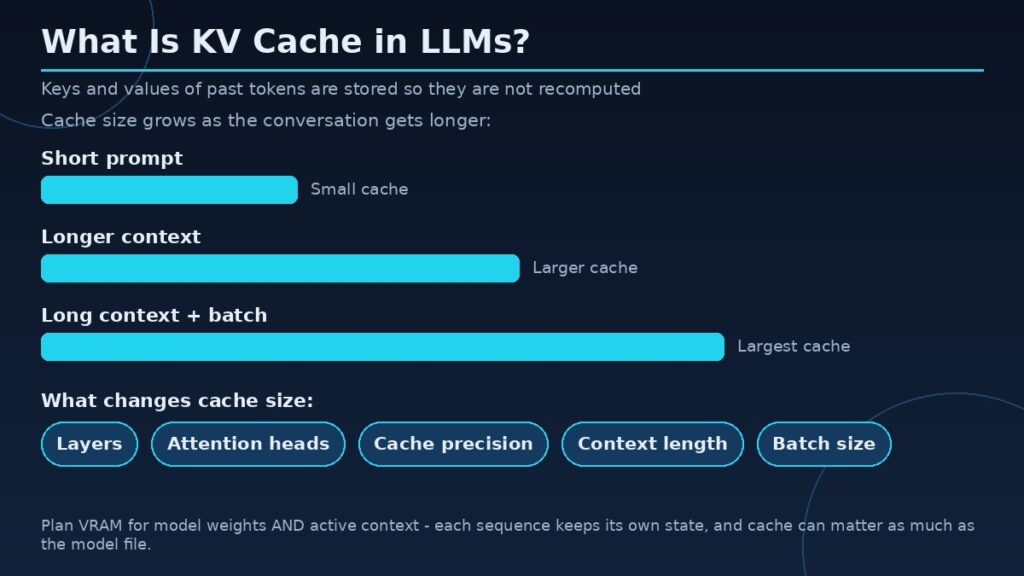
| More layers and attention heads | Increases the rate at which cache grows; depends on layers, heads, head dimensions, and cache data type |
| More concurrent requests | Multiplies cache demand |
| Lower cache precision | Can reduce memory use |
Quick answer
The KV cache is runtime memory used to retain attention information for previously processed tokens. Its size depends on model architecture, context length, batch size, and cache precision.
Key concepts
Before changing hardware or settings, distinguish capacity from allocation and performance. Capacity is the physical amount of local graphics memory installed on the card. Allocation is the amount an application or driver has reserved or committed at a particular time. Active working-set demand is the data that must be available for the current workload to proceed efficiently. Monitoring tools can expose useful clues, but they may report different metrics and should not be treated as interchangeable.
Also distinguish memory capacity from bandwidth and compute throughput. Capacity determines how much data can reside locally. Bandwidth describes the rate at which data can move between memory and the GPU. Compute throughput describes how quickly the GPU can execute operations. A workload may be limited by any one of these factors, or by the CPU, storage, cooling, power limit, or software implementation.
Why attention needs keys and values
Transformer attention projects hidden representations into query, key, and value tensors. Queries are compared with keys to determine how information from earlier tokens should contribute to the current representation, while values carry the information being combined. During token-by-token generation, earlier keys and values can be reused. Retaining them avoids repeating some work and reduces unnecessary computation.
Why the cache grows
As the context gets longer, the model has more prior tokens whose key and value representations may need to be retained. The cache therefore generally grows with sequence length. The rate depends on the number of layers, attention heads or key-value heads, head dimensions, cache data type, and model-specific attention design. Different architectures can have different cache footprints even at similar parameter counts.
Context length is not free
A model’s advertised context window describes a supported sequence length, not a promise that every GPU can use the maximum length at a given batch size. Longer contexts can increase memory requirements and may reduce the number of concurrent sequences that fit. Some systems use sliding windows, grouped-query attention, cache compression, or other optimizations that alter the footprint.
Batch size and concurrency
Serving multiple requests at once can multiply cache demand because each active sequence may maintain its own attention state. Continuous batching improves utilization but needs careful memory scheduling. A system that handles one long conversation may not have enough memory to serve several conversations at the same context length simultaneously.
Cache precision and optimization
Some inference systems support lower-precision KV cache formats or cache quantization. These can reduce memory use, but compatibility and quality implications vary. Offloading or cache eviction can also reduce GPU memory pressure, though data movement may affect latency. Use features documented by the runtime and benchmark them with representative prompts.
How to estimate and measure
A conceptual estimate considers layers, key-value dimensions, tokens, active sequences, and bytes per cached element. Exact formulas vary with architecture and implementation, so use model documentation or runtime tools for precise planning. Measure peak memory after loading the model and during a long generation, not only at startup. Test the longest expected context and concurrency.
Troubleshooting cache-related out-of-memory errors
If a model runs for short prompts but fails on long ones, reduce context length or concurrent batch size as a diagnostic. Check whether the runtime offers cache precision options or a memory budget. Ensure other applications are not consuming GPU memory. Record the exact failure stage because model loading, prompt processing, and token generation can have different memory peaks.
A step-by-step way to investigate
First, write down the exact system configuration. Include the graphics card, memory capacity, driver, operating system, CPU, system RAM, storage, and application version. Record the workload and its settings. In a game, include resolution, texture quality, ray tracing, upscaling, and the scene being tested. In an AI or workstation task, include the model or project, precision, batch size, context length, plugins, and offloading options.
Second, create a baseline using a repeatable task. Close unnecessary background applications, allow the workload to settle, and repeat the same action several times. Capture performance, memory allocation, system RAM use, GPU utilization, and any visible errors or quality changes. Do not rely on one short run. A background update or first-time shader compilation can distort a measurement.
Third, change one setting at a time. This is essential. If several options are changed simultaneously, the cause of an improvement or regression cannot be identified. Save the original settings, test the new configuration, and restore the baseline before testing another variable. When possible, use logs or frame-time captures instead of relying only on a screenshot.
Finally, report what the test does and does not prove. A single application version and one system configuration cannot establish a universal hardware requirement. Explain the test environment, disclose limitations, and distinguish measured results from estimates. This is especially important when publishing advice that readers may use to spend money or change a production workflow.
Common pitfalls
A common pitfall is assuming that a high allocation reading proves the card is out of memory. Software may reserve resources for caching, and different tools may expose dedicated usage, shared usage, committed memory, or budget information. Another pitfall is assuming that more VRAM automatically makes a GPU faster. Additional capacity can prevent a capacity-related problem, but it does not increase the number of shader cores or guarantee higher bandwidth.
A third pitfall is ignoring software changes. Drivers, game patches, AI frameworks, model formats, and operating-system updates can change memory behavior. Record versions and dates, and retest important claims after substantial updates. Avoid undocumented registry edits or utilities that promise to manufacture additional dedicated VRAM; software cannot change the physical memory installed on a discrete graphics card.
Frequently asked questions
Does KV cache use VRAM?
In many GPU inference configurations, yes. The runtime stores attention state in GPU memory, although some systems can offload or manage it differently.
Does KV cache grow with every token?
It generally grows as more context is retained, subject to architecture-specific attention and cache-management strategies.
Can quantization reduce KV cache?
Weight quantization and KV-cache precision are separate choices. Some runtimes support cache quantization, but quantizing model weights does not automatically quantize the cache.
Why does a long prompt cause an out-of-memory error?
Longer context can increase cache and temporary memory requirements. Batch size and runtime overhead also matter.
Can I clear the KV cache?
Ending a conversation or sequence usually releases its associated cache according to the inference system. Exact controls depend on the application.
Conclusion
Plan VRAM for both model weights and active context. For long-context or multi-user inference, cache capacity can be as important as the model file.
The most dependable approach is to define the workload, measure it under controlled conditions, and interpret memory readings alongside performance and system behavior. Use manufacturer documentation for specifications, application documentation for supported settings, and repeatable tests for performance claims. That produces advice that is both more accurate and more useful than a one-number rule.









